From a broad question to a testable quality process
Automated Interface Testing: Safely Validate APIs, Files, and Legacy Data
“How can you test interfaces automatically?” In a workshop, that initially sounded like a question with one method as its answer. In practice, it is too broad. A web API, a JSON file delivered through an SFTP mailbox, and an overnight export from a legacy system all move data—but they need different kinds of checks.
My answer was: start with schema validation—but let the interface determine the rest. That answer became ZEUS Interface Quality, a small, extensible tool for automated quality assurance. After local JSON validation, format-specific file profiles, and a limited HTTP contract, the current implementation now handles SFTP deliveries through directory selection, delivery-ID correlation, claiming, stable snapshots, SHA-256, quarantine, and success archiving. This Project Page records the current design; the Iteration 1 article, Iteration 2 article, Iteration 3 article, Iteration 4 article, and Iteration 6 article show the path from example to executable test.
Current status
This box summarizes the current state for readers who return later. The sections below explain the working approach; the logbook records how it evolved.
- Phase: Iteration 6 complete—local JSON, CSV, fixed-width, HTTP, and SFTP contract validation with a correlated delivery lifecycle
- Implemented: Java 21 CLI with JSON Schema, format-specific file profiles, JDK HttpClient, and key-based SFTP validation with host-key, stability, SHA-256, delivery ID, claim, archive, and optional quarantine checks
- Result: Text or JSON; exit code
0for valid data,1for contract violations, and2when the check cannot be performed reliably - Evidence: public repository, 86 automated tests, JAR smoke tests, local HTTP loopback tests, and embedded SFTP integration tests
- Try it: JSON files: from JSON Schema to CI, CSV and legacy files, HTTP, status, headers, and JSON contracts, safe SFTP file validation, and correlated SFTP deliveries
- Not implemented yet: OpenAPI-derived profiles, OAuth/API-key/mTLS secret management, XML, YAML, mixed-format multi-file deliveries, semantic cross-file rules, and automatic profile generation from DDL, COBOL, or RPG
The short answer
Automated interface testing needs several layers: connectivity and authentication, parsing, a schema or contract, business rules, and—where required—comparison with expected or reference data.
- Identify the interface type and transport.
- Define a versioned schema or formal interface contract.
- Use an adapter for HTTP, file transfer, or the legacy format.
- Parse the incoming data and validate it against the contract.
- Check business rules, quantities, cross-references, and duplicates as needed.
- Produce a machine-readable result with a failure path, file, request ID, or record number.
Rule of thumb: A schema answers “Is this message structurally allowed?” A complete interface test also answers “Could I retrieve it safely?” and “Is it meaningful for the business?”
That is the overall approach. The current tool covers local input, contract validation, HTTP checks, and reporting; transport and business layers grow as separate adapters and rules.
A common misconception
“If the file matches the schema, the interface works.” That is only one part of the path. A file can be structurally valid yet unusable because it is in the wrong directory, was delivered twice, or was decoded with the wrong encoding. An API can return valid JSON and still send the wrong HTTP status, an incompatible version, or inconsistent pagination. Schema validation is central, but it is not the entire test plan.
What should actually be tested?
A useful automated test separates the layers. That prevents one green test run from promising more than it actually checked.
| Layer | Question | Example |
|---|---|---|
| Transport | Is the communication path reachable? | HTTP endpoint, SFTP directory, port, timeout, TLS or host-key verification |
| Authentication | Is the test client allowed to connect? | API key, OAuth 2.0 client credentials, mTLS, Basic Auth as an exception, SSH key |
| Parsing | Can the response be read as data? | JSON, XML, CSV, UTF-8, EBCDIC conversion, fixed-width, ZIP |
| Structure | Does the message match the agreed contract? | Required fields, types, ranges, ordering, additional fields |
| Business meaning | Is the message plausible? | Start date precedes end date, totals reconcile, status transition is allowed |
| Completeness | Is a delivery or record missing? | Expected file, record count, sequence without gaps |
| Repeatability | What happens on retry or duplicate delivery? | Idempotency key, duplicate detection, safe restart strategy |
The first two iterations focused on parsing and structure. Iteration 3 adds a small HTTP transport slice. The remaining layers stay separate: not every legacy file needs OAuth, and not every API needs a filename check. A common result model keeps the reports comparable.
Interface types and starting points
Web APIs, files, and legacy exports are the three main areas of the project. We started with a local JSON file, added CSV and fixed-width profiles, then implemented a deliberately limited HTTP adapter and a bounded SFTP adapter. Directory polling, multi-file correlation, and message queues remain later topics.
1. Web APIs: contract plus behavior
An HTTP response is more than a data object. Method, URL, headers, status code, timing, authentication, and error format are part of the contract. A schema can check that customerId is a string and items is an array; it cannot decide by itself whether an unauthorized GET /orders/123 should return 403 or 404.
That is why OpenAPI is a useful outer HTTP contract. Its data models can use JSON-Schema-compatible rules, while contract tests cover methods, statuses, headers, requests, and responses. The validator is one part of contract testing—not a replacement for it.
2. Files: read safely, then validate
A file delivered through FTP or SFTP has properties outside its content: naming, location, delivery window, compression, encoding, checksum, and a signal that writing is complete. A valid CSV can still be truncated if the sender is uploading it while the receiver starts reading.
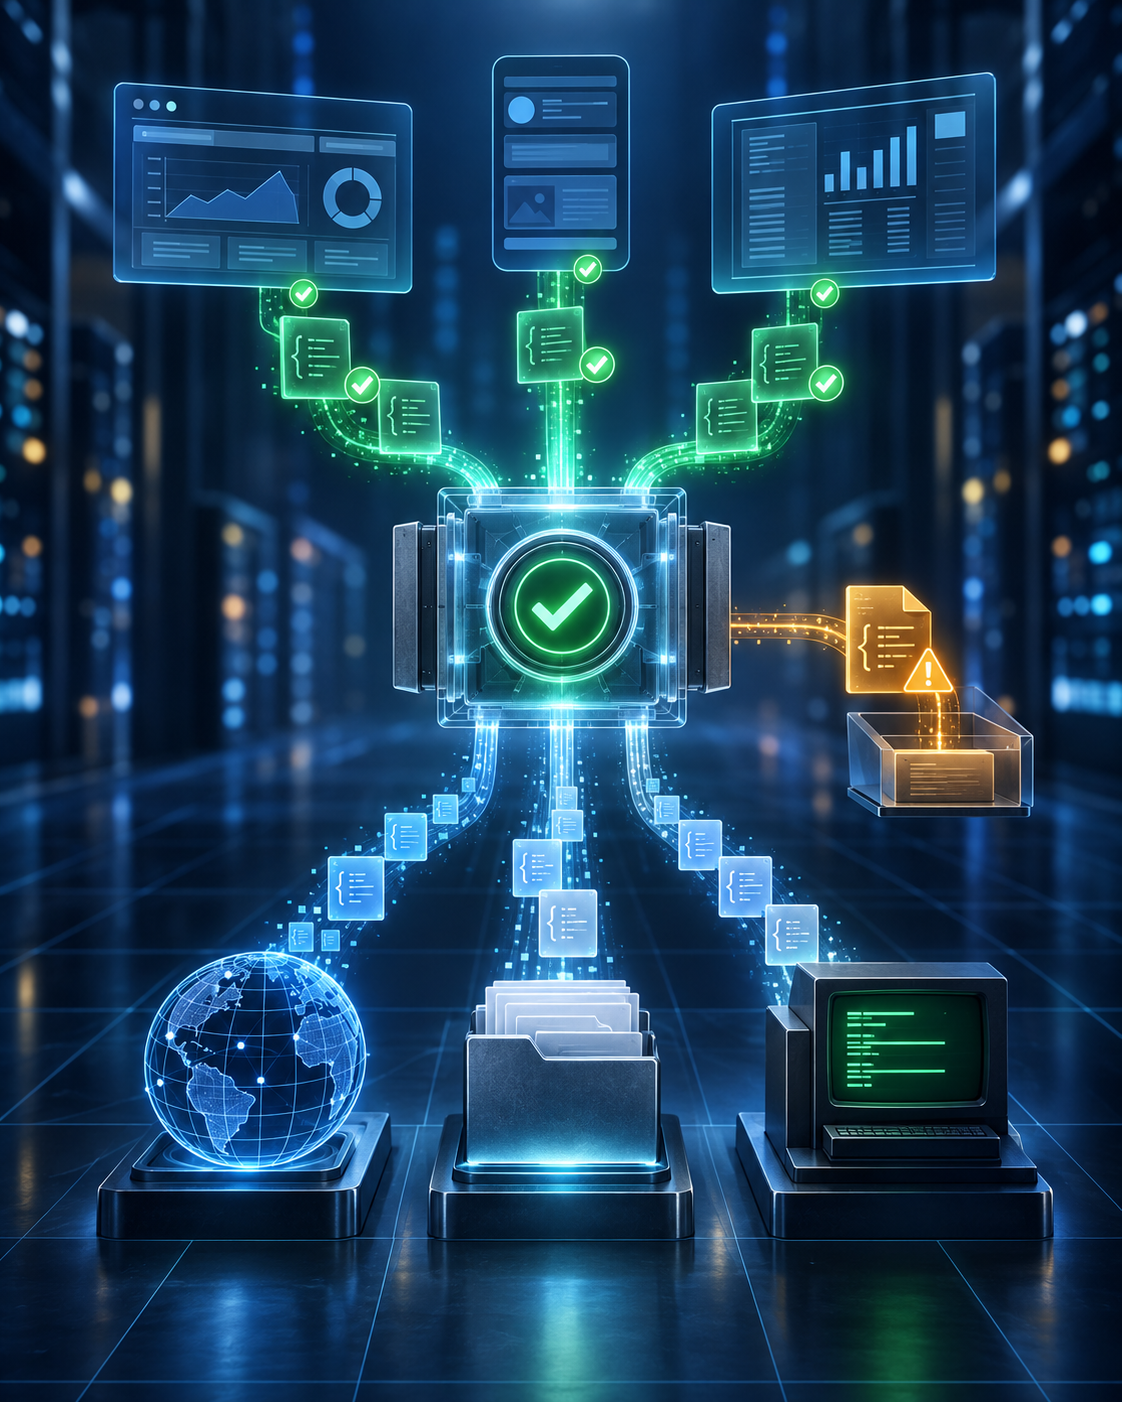
A complete file adapter therefore needs a sequence: find the file, verify stability or a marker, transfer it safely, record hash and size, parse it, validate it, move it to quarantine or processing, and report the result.
3. Legacy interfaces: turn reality and rules into a contract
Older interfaces often lack a maintained schema. Samples, DDL scripts, field descriptions, COBOL copybooks, RPG source such as RPGLE, or an existing importer are useful evidence—but they are not automatically the business truth. A column may be VARCHAR(10) in DDL and still allow only a small set of status codes.
The sensible order is to derive a schema draft, review it with the business, approve it deliberately, and store it as a versioned contract. Automatic generation saves work; it does not decide which deviation is an error and which is an accepted exception.
Which schema format fits?
The obvious formats serve different purposes. The question is which part of the contract needs to be described.
| Format | Strength | Role in this project |
|---|---|---|
| JSON Schema | Structural rules, ranges, and formats for JSON data | Implemented for file and HTTP request/response data |
| OpenAPI | HTTP routes, methods, parameters, statuses, security, and data models | Candidate outer contract for a fuller API adapter |
| XML Schema / XSD | Structure, types, namespaces, and cardinalities for XML | Future XML adapter; existing XSDs should be used directly |
| YAML Schema | Possible YAML-specific contract model | Open for evaluation |
| Adapter profile | Format-specific rules for CSV, fixed-width, or proprietary data | Implemented for CSV and fixed-width; results map to the shared model |
🟢 Our first architectural decision
JSON Schema Draft 2020-12 is the data contract; CSV, fixed-width, and HTTP each use an appropriate adapter profile. OpenAPI remains a possible outer contract for a fuller API adapter. Technology-neutral does not mean using every technology at once; it means keeping concrete library choices out of the core.
Why JSON Schema is our starting point
JSON Schema is practical for a first step because both the contract and the test data can be JSON. It describes types, required fields, arrays, ranges, patterns, and compositions. It can be versioned, checked, and validated in many languages.
Our first executable example describes a delivery with an ID, quantity, email address, and postal address:
{
  "$schema": "https://json-schema.org/draft/2020-12/schema",
  "$id": "delivery.schema.json",
  "title": "Delivery",
  "type": "object",
  "additionalProperties": false,
  "required": ["deliveryId", "quantity", "email", "address"],
  "properties": {
    "deliveryId": { "type": "string", "minLength": 1 },
    "quantity": { "type": "integer", "minimum": 1 },
    "email": { "type": "string", "format": "email" },
    "address": { "$ref": "refs/address.schema.json" }
  }
}
The address lives in refs/address.schema.json. The example enables format assertions explicitly, so an obviously invalid email is reported as a contract violation. That checks the format—not whether a mailbox exists or can be reached.
Architecture: a small core with open adapters
The current implementation is one Java 21 Maven module. The core defines project-owned result objects and a validator interface. JSON, CSV, fixed-width, and HTTP adapters encapsulate their parsers and profile rules; the CLI uses Picocli, and separate writers produce text or JSON. Spring Boot is not required for this use case.
The shared result contract stays intentionally small: status, valid, and an ordered list of findings. Source, timestamp, schema ID, hash, and HTTP metadata are possible future additions, not current fields. Secrets, tokens, and complete personal payloads should never be copied into a report by default.
Testing files automatically
Iteration 1 validated an existing local JSON file. Iteration 2 added local CSV and fixed-width files; Iteration 3 adds a local HTTP call described by a profile; Iteration 4 retrieves and validates exactly one stable SFTP file; Iteration 5 selects exactly one matching file from an SFTP directory. Multi-file lifecycles, claim/lock protocols, and operational orchestration remain separate concerns.
A complete file flow is larger than a schema check
- Check the expected path, filename, delivery window, and extension.
- Confirm that the file is complete—through a temporary suffix, done marker, stable size, or checksum.
- Transfer it safely and record technical metadata.
- Validate encoding and file format before applying business rules.
- Parse records and validate them against the format profile.
- Check business rules, quantities, and duplicates.
- Move failures to quarantine without altering the original and produce a traceable report.
Testing web APIs with contracts and authentication
The current API adapter focuses on one known endpoint and checks a limited but useful set of properties:
- reachability, TLS, and timeout behavior;
- HTTP method, URL, headers, and content type;
- expected status codes for success and defined failure cases;
- request and response schemas;
- authentication, pagination, rate limits, correlation IDs, and repeatability as future layers.
Authentication should be represented by a profile such as oauth2-client-credentials, api-key, mtls, or basic. Concrete values belong in environment variables, a secret store, or CI configuration. Neither schemas nor reports should contain real tokens, private certificates, or passwords.
Iteration 3 already covers a valid request, a request violation, an unexpected status, a missing required header, an incorrect response type, malformed JSON, and a transport failure. Authorization profiles, rate limits, and multi-step business scenarios remain later iterations.
Describing legacy interfaces after the fact
A schema created after the system went live is not an inferior substitute for an official specification. It is often the most realistic way to turn implicit knowledge into an explicit, testable contract.
- Collect samples and DDL.
- Draft the schema and mark uncertain assumptions.
- Ask domain owners about required fields, codes, and ranges.
- Define valid and invalid fixtures.
- Approve version 1 and add it to the test runs.
- Treat new deviations as deliberate schema changes, not as silent “make it green” exceptions.
🟢 A good legacy rule
Samples can suggest rules; they cannot invent business rules. An automatically generated schema should remain visibly a draft until a domain review turns it into an approved interface contract.
From validation to quality assurance
A useful result separates two questions: Did the data violate the contract, or could the check not be performed reliably? The CLI expresses that boundary with three outcomes:
| Exit code | Result | Meaning |
|---|---|---|
| 0 | VALID, valid: true |
The input satisfies the selected JSON Schema or format profile. |
| 1 | INVALID, valid: false |
Readable JSON, CSV, fixed-width, or HTTP data violates a rule; findings explain why. |
| 2 | Error on stderr, no JSON result | For example, invalid syntax, missing file, invalid profile, or a disallowed schema reference. |
Findings name a data path, schema path, keyword, and message. Their ordering is stable. Automation can therefore compare the actual report with an expected example instead of checking only “red or green.”
The idea as a living Project Page
The article is meant to grow with the project. The Project Page records the current position, the logbook preserves the chronology, and a sub-article appears only when an iteration has its own fixtures, code, measurements, or meaningful failed attempt. That keeps the architecture honest: later work does not look as if it had been known on day one.
The first development iterations
The ZEUS Interface Quality repository now contains four completed, executable vertical slices. The next entries are options, not promises of existing features.
| Iteration | Result | Why this order? |
|---|---|---|
| 0 – Foundation · complete | Project idea, boundaries, repository, and toolchain | Create a shared baseline |
| 1 – JSON file · complete | Java CLI, local schemas, text/JSON, exit codes 0/1/2, fixtures, regression tests, and CI | Make input-to-result reproducible |
| 2 – CSV/legacy file · complete | CSV and fixed-width adapters with profiles, shared rules, AUTO detection, fixtures, and reports | Keep format rules separate from the result contract |
| 3 – HTTP adapter · complete | Local HTTP profile, request/response schemas, status/header/content-type checks, and no redirects | Join transport and data contract in one reproducible slice |
| 4 – SFTP adapter · complete | Host-key verification, stable snapshot, SHA-256, content delegation, and optional quarantine | Include the file lifecycle in a controlled slice |
| 5 – SFTP directory selection · complete | Directory listing, basename regex, bounded waiting, and exactly one matching regular file | Reject ambiguous deliveries safely |
| 6 – SFTP delivery lifecycle · complete | Delivery ID, primary/companion correlation, claim, recovery, archive, quarantine, and lifecycle metadata | Take ownership of related deliveries safely |
| 7 – Derivation · open | Schema drafts from samples and DDL with domain review | Describe legacy inventory step by step |
| 8 – Operational maturity · open | Additional reports, operational metadata, and documented limits | Support real use instead of adding formats for their own sake |
Repository, CI, and the shared JSON report remain the foundation. Iteration 6 combines directory selection with delivery-ID correlation, claiming, recovery, success archiving, and quarantine. The SFTP adapter now checks not only the content but also the delivery’s transition through the validation process. OpenAPI derivation, secret management, mixed-format deliveries, and cross-file business rules can now be evaluated separately.
Logbook
Newest entries appear first. Earlier entries remain as historical snapshots; the current status belongs at the beginning of the page.
September 29, 2026 · Iterations 5 + 6 · Correlated SFTP delivery lifecycle
Decision: The planned directory selector is combined with a delivery ID, optional companion file, atomic claim, recovery, success archive, and quarantine in a version-3 profile.
Reason: One matching file does not prove a complete delivery. The ownership boundary must be visible before download, and a restart must not silently select a different delivery.
Impact: The full build now contains 86 tests with 0 failures and 2 expected skips. An embedded SFTP server exercises the production JSch transport, and the operational JSON report can expose the lifecycle.
Publication: Directory selection is not published as a standalone Iteration 5 article; it is explained within the new SFTP lifecycle article.
September 25, 2026 · Iteration 4 · Bounded SFTP adapter
Decision: The next vertical slice validates exactly one SFTP file through a local profile. Host key and private key remain explicit; a stable remote snapshot, optional SHA-256 check, and delegation to JSON, CSV, or fixed-width validators define the run.
Reason: A successful download proves neither a complete delivery nor a trusted host or valid content. The implementation therefore separates trust, stability, integrity, and content outcomes.
Impact: 76 tests cover valid files, changing metadata, digest mismatches, content findings, quarantine, and temporary downloads. Iteration 4 explains the profile, invocation, limits, and reproducible evidence.
Still open at that time: Directory selection, multi-file correlation, password or agent authentication, success archiving, and production-style live-server tests remained separate decisions.
September 21, 2026 · Iteration 3 · Limited HTTP adapter
Decision: The next vertical slice connects a local JSON request to an HTTP or HTTPS call. A version-one profile describes method, URL, headers, expected status, response headers, media type, timeout, and local request/response schemas.
Reason: An API contract is not only JSON. Status, required headers, and transport behavior must be visible. The JDK HttpClient provides a small standard foundation, while local loopback tests remain reproducible and avoid an external dependency.
Impact: 70 tests, the package build, and JAR smoke tests now cover four input paths. Request violations are caught before sending; response violations remain INVALID, and transport/profile errors remain exit 2. The Iteration 3 article shows the profile, invocation, and findings.
Still open: OpenAPI parsing, OAuth/API-key/mTLS secret management, redirects, streaming, multi-step calls, SFTP, business rules, and operational maturity.
September 17, 2026 · Iteration 2 · Shared rules and AUTO detection
Decision: CSV and fixed-width adapters share scalar-rule validation. The CLI defaults to AUTO, detects the adapter from the profile’s format field, and still supports explicit selection.
Reason: Required values, types, lengths, and ranges should not drift between adapters. Automatic selection shortens normal commands, while explicit formats remain useful in scripts and troubleshooting.
Impact: 64 tests, package and JAR smoke tests, and CI covered the shared rules and AUTO paths. The Iteration 2 article documents the boundaries.
Still open at that time: transport access, API adapters, automatic derivation from DDL/copybooks/DDS/RPGLE, byte-level rules, and business rules.
Open questions
- Which OpenAPI or secret-management extension is the next clearly bounded HTTP step?
- Which context should an operational report add without unnecessarily expanding the contract?
- What file-size, runtime, and resource limits are needed before production use?
- When does YAML need its own contract instead of being parsed into a JSON-compatible model?
- What quarantine and retry model is the minimum standard for file adapters?
- Which license should the first public release use?
What schema validation does not do
A schema cannot infer business meaning, move data from a counterparty, or repair a broken credential. It also does not answer availability, security, performance, compatibility, completeness, or retry questions. Those are separate test layers—and keeping them separate is what makes the approach maintainable.
Glossary
Key terms used in this project.
- Adapter
- A component that connects a concrete transport or data format to the shared validation flow.
- API
- An application programming interface, here usually a web API exposed through HTTP.
- Contract testing
- Testing whether an interface honors the agreement between consumer and provider.
- DDL
- Data Definition Language: SQL statements describing tables, columns, types, and constraints.
- Fixture
- Reproducible test data, such as a valid JSON file or an intentionally invalid CSV record.
- JSON Schema
- A JSON-based schema format for describing and structurally validating JSON data.
- Legacy interface
- An established integration path with proprietary formats, limited specification, or historical rules.
- OpenAPI
- A specification for HTTP paths, methods, parameters, responses, security, and data models.
- Quarantine
- A separate storage or status area for failed messages so they are not processed accidentally.
- Schema
- A formal description of the structure and values a message or file may contain.
- XSD
- XML Schema Definition, a standard schema format for XML structure, types, and cardinalities.
Frequently asked questions
Is JSON Schema enough for every interface?
No. JSON Schema is a strong starting point for JSON data. HTTP contracts also need transport and API information; XML has XSD; CSV and fixed-width data need parser profiles. The shared layer should be the result model, not necessarily the input format.
Can a CSV file be checked with JSON Schema?
After parsing, it can be mapped to JSON. For the first file path, however, the CSV adapter owns encoding, delimiter, header, and column rules, while the fixed-width adapter owns record length and positions. Both produce the same report shape.
Can a schema be generated from sample data?
Yes, as a draft. Multiple samples help infer types, required fields, and ranges, but a domain review must decide what is actually allowed.
What else needs testing for FTP and SFTP?
Reachability, authentication, host-key or certificate checks, path, filename, delivery window, complete transfer, checksum, size, quarantine, and retry behavior. Only then should the file content be validated.
Which authentication should an API adapter support?
Useful profiles include API key, OAuth 2.0 client credentials, and mTLS. Basic Auth may be needed for compatibility, but only over a protected connection. Secrets belong in secure runtime configuration, never in schemas or logs.
Is a green schema test an integration test?
Not automatically. A local fixture checks parsing and the schema. An integration test also exercises a real or realistic endpoint, transport, authentication, and often retry and failure behavior.
Can I try the current version?
Yes. The Iteration 1 article walks through the local build and three example files. You need Git and JDK 21; the Maven Wrapper supplies Maven. This is a development state, not a production release.
Why make this a Project Page?
Because the best architecture emerges from real examples. The page holds the current state, the logbook keeps the chronology, and sub-articles add depth only when an iteration has substance.
Conclusion: automated interface testing makes contracts testable
The question is too broad as a one-line question—and that is exactly why it is a good starting point. APIs, files, and legacy interfaces have different transports, formats, and failure modes.
Schema validation is the shared core: it makes structural compliance visible. Reliable quality assurance adds transport, authentication, parsing, business rules, completeness, and repeatability.
The project now covers JSON Schema, CSV and fixed-width profiles, a limited HTTP adapter, and a key-based SFTP delivery lifecycle with stability, digest, claim, archive, and quarantine checks. OpenAPI, secret management, XSD, and additional operational workflows remain deliberate future extensions.
The evidence is growing: one CLI distinguishes valid data, contract violations, and technical failures across five input paths. Follow Iteration 1, Iteration 2, Iteration 3, Iteration 4, and Iteration 6.
Sources & further reading
Technical and editorial status: September 29, 2026. This Project Page describes the Iteration 6 state on main and the combined presentation of Iterations 5 + 6.


 tiny-tool.de
 tiny-tool.de